According to a 2025 survey conducted by Parseur and QuestionPro, employees in the United States spend more than nine hours per week on manual data entry, costing businesses an average of USD 28,500 per employee each year. To address this challenge, an AI document extraction solution can automatically identify, classify, and convert documents into structured data, significantly reducing processing time and costs. This article explains what the solution is, how it works, its real-world use cases, and the key steps involved in building one. Test 123
1. What is AI document extraction?
AI document extraction is a technology that uses machine learning and natural language processing to automatically extract data from unstructured documents such as PDFs, images, and emails.
Unlike traditional OCR, which primarily focuses on character recognition, this technology can also analyze context to identify the exact information that needs to be captured. The extracted data is then automatically converted into JSON or other standardized structured formats.
_2026-08-27-17-55-55-755.webp)
AI-powered document data extraction
2. How AI document extraction works?
AI document extraction processes documents through four sequential stages, from input standardization to structured data output. Each stage handles a distinct layer of analysis to preserve both the document content and its context.
Step 1 - Document Ingestion and Pre-processing
The system receives various document types, including PDFs, scanned images, emails, and forms, through file uploads, APIs, or storage repositories. The input is then standardized by splitting pages, correcting image orientation, deskewing scans, enhancing image quality, or reading an existing text layer within the PDF. This ensures that all documents are converted into a consistent format before further analysis.
Step 2 - Layout Detection and Document Understanding
Once the document has been standardized, OCR identifies the characters and their positions on the page. A vision-language model (VLM) or document understanding model then analyzes the layout to detect headings, paragraphs, tables, data fields, and key-value pairs. This is a key distinction from traditional OCR, which can recognize text but cannot understand the relationships between different pieces of information.
Step 3 - Field Extraction and Entity Recognition
Based on the detected layout, NLP, LLMs, or specialized models extract the required fields, such as dates, monetary values, supplier names, and contract terms. Each extracted field is typically assigned a confidence score indicating the reliability of the result. The system also normalizes values according to a predefined schema to ensure a consistent and structured output.
Step 4 - Validation, Human-in-the-loop, and Output
The extracted data is validated against business rules, required formats, and reference information. Fields with low confidence scores, missing values, or rule violations are flagged for human review. Once verified, the data is converted into structured formats such as JSON or XML and integrated with downstream systems, including ERP, CRM, and RPA workflows.
_2026-08-27-17-55-55-912.webp)
How AI extracts data from documents
3. Benefits of AI document extraction
According to Salesforce, 70% of data and analytics leaders report that a large amount of valuable information remains locked in unstructured data. AI document extraction helps convert this information into usable, structured data.
1 - Broader coverage
AI document extraction can process structured, semi-structured, and unstructured documents, including invoices, contracts, emails, scanned images, and handwritten content. By combining OCR with layout analysis and language models, the system can identify the correct data fields even when document templates, information placement, or formatting vary. As a result, it supports a significantly broader range of documents than traditional OCR.
2 - Improved data quality
AI document extraction improves data quality by automatically identifying information and mapping it to the correct fields, reducing typing errors, omissions, and incorrect data placement. After extraction, the data can be validated against required formats, reference sources, and confidence scores. Fields with low confidence are routed to employees for verification before being stored in the system.
3 - Scalability without additional headcount
AI document extraction can process multiple documents simultaneously and handle sudden increases in volume without requiring a proportional increase in data-entry staff. Enterprises can scale processing resources while employees focus primarily on exceptions and low-confidence results. However, actual scalability still depends on the system architecture, service limits, and data governance requirements.
_2026-08-27-17-55-56-021.webp)
Large-scale AI document processing
4. Key use cases of AI document extraction across industries
AI document extraction can be applied to a wide range of workflows involving the processing of large volumes of documents. Below are several common use cases across industries such as finance, healthcare, logistics, and e-commerce and retail.
1 - Finance and Banking
In finance and banking, data extracted from documents can be transferred directly into accounting, credit management, and customer verification systems. Typical use cases include:
Invoice processing: AI extracts supplier names, invoice numbers, issue dates, line items, tax amounts, and totals, then sends the data to accounting software or ERP systems. For example, TMA’s Automatic Invoice Processing Agent can reconcile invoices against purchase orders and goods receipts through a three-way matching process.
KYC and AML: The system captures names, dates of birth, addresses, identification numbers, and document expiration dates from identity records to support customer onboarding, identity verification, and risk assessment. For finance-focused AI agent solutions, TMA recommends combining document extraction with KYC checks and fraud detection processes.
Loan application processing: AI consolidates borrower information, income, financial obligations, and collateral details from loan applications and supporting documents, then transfers the data into a loan origination system. TMA describes an approach that combines document data extraction with credit scoring to support credit assessment and approval.
Financial report extraction: AI identifies financial metrics, tables, and relationships between data points in balance sheets, income statements, and cash flow statements. For example, TMA’s Finance Document Intelligence solution uses Azure AI to extract and classify data for financial analysis and reporting.
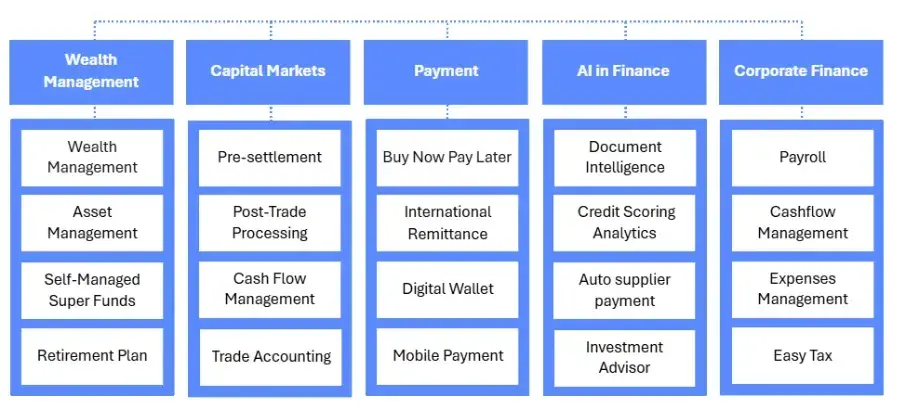
_2026-08-27-17-55-56-424.webp)
AI-powered financial document extraction
2- Healthcare
In healthcare, extracted data can be transferred into electronic health record (EHR) systems, insurance platforms, or pharmaceutical management systems. When protected health information is processed in the United States, the entire workflow must comply with HIPAA requirements for encryption, access control, audit logging, and data sharing.
Medical records: AI identifies patient information, diagnoses, test results, and treatment plans from medical records, then converts them into structured data that can be used in EHR systems. For example, TMA’s FHIR Transformation Service uses NLP to extract data from PDFs, physician notes, and emails and transform it into FHIR resources.
Insurance claims: The system extracts policyholder information, treatment details, claim amounts, and supporting documents to support the claims assessment and approval process. TMA’s AI for Insurtech solution uses OCR to detect stamps and convert data from invoices, receipts, and insurance documents into JSON.
Prescription forms: AI identifies the patient’s name, medication name, strength, dosage instructions, and prescriber information for entry into treatment records or pharmacy systems. In its Healthcare OCR solution, TMA extracted data from prescriptions, laboratory results, and more than 30 types of medical devices to create structured electronic records.
_2026-08-27-17-55-56-694.webp)
AI-powered healthcare data digitization
3- Logistics & Supply Chain
In logistics and supply chain operations, data extracted from shipping documents can be synchronized with transportation management systems (TMS), ERP platforms, or logistics management systems. Key applications include:
Bill of lading: AI extracts the bill of lading number, shipper, consignee, shipping route, container number, cargo type, quantity, and weight to create or update shipment records. In one of TMA’s case studies, the system captured shipment information, arrival dates, and container numbers, then updated the client’s logistics system directly.
Customs documents: AI captures the country of origin, declared value, number of packages, declared HS codes, and importer/exporter details from customs declarations and supporting documents. TMA’s document extraction solution can also link data across customs declarations, commercial invoices, and packing lists before transferring it into the customs clearance workflow.
Purchase orders: The system extracts the PO number, supplier details, SKU, quantity, unit price, and delivery date to support procurement and payment processes. For example, TMA’s Automatic Invoice Processing Agent uses purchase order data to reconcile invoices with goods receipts before the transaction proceeds to the next stage.
_2026-08-27-17-55-56-800.webp)
Automating logistics and supply chain documents
4- E-commerce & Retail
In e-commerce and retail, extracted data can be integrated into product information management (PIM), order management, warehouse management, or ERP systems. The following use cases align well with the e-commerce solution ecosystem offered by TMA.
Product catalog ingestion: AI extracts SKUs, product names, brands, prices, specifications, and variants from supplier documents, then maps these fields to the retailer’s taxonomy. For example, the data can be standardized before being imported into a B2B e-commerce platform developed by TMA for centralized management of product catalogs, orders, and customer information.
Supplier invoices: AI captures supplier IDs, invoice numbers, products, taxes, discounts, total amounts, and payment due dates, then transfers the data into the ERP system. TMA’s invoice processing solution can combine this information with purchase orders and goods receipts as part of the payment control workflow.
Returns processing: AI extracts the order number, SKU, return reason, and refund method from return forms, emails, or proof-of-purchase documents, then sends the information to the order management system. When integrated with TMA’s Customer Service AI Agent, the system can receive return requests, retrieve order details, and escalate cases requiring further handling to the appropriate staff.
_2026-08-27-17-55-57-132.webp)
AI-powered data processing from procurement to returns
Your industry has unique document workflows.
We build custom AI extraction - not one-size-fits-all tools.
5. Top 5 document extraction solutions in 2026
Below are five leading document extraction solutions selected for their document processing capabilities, model customization options, and integration with enterprise systems.
1 - Microsoft Azure AI Document Intelligence
Azure AI Document Intelligence uses OCR and AI to recognize printed text, handwriting, tables, selection marks, key-value pairs, and document layouts in PDFs and images. Its prebuilt models can extract specific fields such as invoice numbers, issue dates, supplier details, total amounts, account information, and contract terms. Enterprises can also create custom models and custom classifiers for their own document templates, then deliver normalized data to applications through APIs.
TMA Solutions has implemented this tool within its Finance Document Intelligence architecture. The system ingests, classifies, and extracts data from financial documents before enriching, storing, or transferring the information to search and analytics platforms.
Applicable industries: Finance and Banking, Insurance, Healthcare, Accounting, Retail, Legal, and the Public Sector. The tool is well suited to invoices, bank statements, mortgage documents, contracts, and identity documents, particularly for enterprises already using the Microsoft Azure ecosystem.
API/Integration Notes: Supports a wide range of REST APIs and SDKs for multiple programming languages, including Python, .NET, Java, and JavaScript. It also integrates seamlessly with the Microsoft ecosystem, including Azure Logic Apps, Power Automate, and Azure Storage.
2 - Google Cloud Document AI
Google Cloud Document AI processes documents through specialized processors. Enterprise Document OCR recognizes text and document layouts, Form Parser extracts tables, checkboxes, and key-value pairs, Custom Classifier identifies document types, and Custom Splitter separates document packages into individual files. For industry-specific documents, enterprises can define a field schema and train a Custom Extractor to return structured results through APIs.
Applicable industries: Finance and Lending, Accounting, Procurement, Human Resources, and Logistics. Common document types include bank statements, loan applications, invoices, payslips, purchase orders, and shipping documents.
API/Integration Notes: Provides REST APIs, RPC APIs, and robust client libraries for languages such as Python, Java, and Node.js. It can also connect directly with Google data services, including Google Cloud Storage and BigQuery, to automate data processing and analytics workflows.
3 - Amazon Textract
Amazon Textract recognizes both printed and handwritten text while preserving relationships between labels and values in forms, as well as between rows and columns in tables. Its Queries feature allows the system to retrieve specific fields directly, such as a customer name or contract number. Specialized APIs also support invoices, receipts, identity documents, and mortgage loan packages. Results include location data and confidence scores, allowing enterprises to perform further validation or automate downstream processes.
Applicable industries: Financial Services, Insurance, Healthcare and Life Sciences, and the Public Sector. Common use cases include loan applications, insurance claims, patient intake forms, tax documents, and administrative records. The tool is particularly suitable for organizations that need to integrate document extraction with applications and workflows running on AWS.
API/Integration Notes: Easily accessible through AWS SDKs, the AWS CLI, and REST APIs. It integrates seamlessly with Amazon S3, can trigger automated workflows through AWS Lambda, and works with Amazon A2I (Augmented AI) to support human-in-the-loop review and verification.
4 - ABBYY Vantage
ABBYY Vantage is a low-code/no-code intelligent document processing platform designed for structured, semi-structured, and unstructured documents. Enterprises can use prebuilt Document Skills or create custom skills to classify and split documents, recognize handwriting, barcodes, and checkboxes, and then extract and validate the required data. Low-confidence fields can be routed to employees for review before the information continues through the workflow.
Applicable industries: Financial Services, Insurance, Transportation and Logistics, Supply Chain, Healthcare, and Finance and Accounting. The platform is well suited to KYC, customer onboarding, loan processing, insurance claims, accounts payable, invoices, and shipping documents. Extracted data can be transferred directly into ERP, RPA, BPM, or ECM systems.
API/Integration Notes: Provides a comprehensive REST API. A key strength is its range of out-of-the-box connectors for fast integration with RPA platforms such as UiPath and Blue Prism, as well as ERP, BPM, and ECM systems, with minimal coding required.
5 - UiPath IXP
UiPath IXP combines Document Understanding, Generative Extraction, and Communications Mining. Document Understanding processes forms, invoices, and purchase orders. Generative Extraction retrieves information from contracts and unstructured reports, while Communications Mining analyzes the content, intent, and context of emails and messages. Uncertain results can be routed to employees for verification before being passed to AI agents, RPA robots, or automated workflows on the UiPath Platform.
Applicable industries: Banking and Financial Services, Insurance, Healthcare, the Public Sector, Manufacturing, Finance and Accounting, Supply Chain, and Human Resources. The platform is suitable for claims processing, supplier invoices, financial records, HR requests, onboarding, and workflows that involve both documents and business communications.
API/Integration Notes: Integrates natively with UiPath Studio and Orchestrator. It also provides extensible APIs for flexible integration with enterprise software systems and automated workflows outside the UiPath ecosystem.
6 - Parseur
Parseur is a powerful data extraction solution designed to capture information from emails, PDFs, and other text-based documents. The platform combines template-based recognition with AI to automatically extract data from incoming document and communication flows. Parseur stands out for its intuitive interface, which allows users to set up automated extraction workflows quickly without requiring programming knowledge.
Applicable industries: Real Estate, E-commerce, Delivery and Logistics Services, and Recruitment, including CV and candidate information processing.
API/Integration Notes: Provides robust Webhooks and REST APIs. The platform also offers native integrations with Zapier, Make (Integromat), and Power Automate, enabling extracted data to be automatically transferred to thousands of CRM systems, databases, Google Sheets, and other applications.
7 - Docparser
Docparser is a specialized platform that helps businesses convert PDF and Word documents into structured data. It uses Zonal OCR combined with flexible rule-based extraction to let users define the exact areas from which data should be captured, such as invoice numbers, tables, or customer names, directly on a sample document.
Applicable industries: Finance and Accounting, Logistics, Supply Chain Management, and Order Processing, including purchase orders and invoicing.
API/Integration Notes: Supports REST APIs and Webhooks. Automated data ingestion can be configured easily from cloud storage services such as Google Drive and Dropbox, while connections to ERP and CRM systems can be established through Zapier or direct API integration.
_2026-08-27-17-55-57-270.webp)
UiPath IXP uses AI to process documents and conversations
Every business has unique data structures. If none of these off-the-shelf concepts match your exact workflow, TMA can engineer a dedicated parser tailored to your specific documents.
Ready to build your AI document extraction system?
TMA has delivered AI/ML solutions across 30 countries. We scope, architect, and build to production - not prototypes.
No sales pressure. Just a conversation.
6. How to choose AI document extraction solutions for 2026
To ensure smooth and secure automation, enterprises should evaluate potential solutions against the following five core criteria:
1 - Define the documents and workflows you need to support
Each document type has its own structure, format, and level of complexity. Without clearly defining the documents and workflows to be supported from the outset, an enterprise may choose a solution with strong OCR capabilities that does not fit its actual business processes or cannot capture critical data fields. Organizations should therefore identify the document types to be processed, such as invoices, contracts, forms, medical records, and identity documents, as well as how the extracted data will be used downstream.
2 - Prioritize solutions with clean APIs and fast developer onboarding
AI document extraction solutions often need to integrate with ERP, CRM, document management systems, or internal business applications. Complex APIs or unclear technical documentation can increase integration time, development costs, and dependence on the technology provider. Enterprises should prioritize platforms with well-designed APIs, comprehensive documentation, and a streamlined onboarding experience for developers.
3 - Test extraction accuracy and metadata quality on real samples
Accuracy demonstrated on vendor-provided sample documents may not reflect performance on an enterprise’s actual data. Organizations should therefore test the solution using their own invoices, contracts, forms, and business records to determine whether it can accurately extract the required content, data fields, and metadata.
4 - Check security, governance, and integration readiness
Enterprise documents may contain customer information, financial records, or sensitive internal data. Organizations should assess how the solution stores, encrypts, accesses, and governs this information. They should also confirm that the platform can be integrated securely with the existing infrastructure and comply with relevant data protection and governance requirements.
5 - Run an end-to-end proof of concept to validate fit
A tool may perform well at individual stages but still fail to operate effectively across the complete workflow. Before deploying at scale, enterprises should run an end-to-end proof of concept using the actual process: document ingestion → recognition → data extraction → validation → transfer to the target system.
This allows organizations to evaluate not only extraction accuracy, but also processing speed, integration capabilities, the achievable level of automation, and the amount of manual work that remains.
_2026-08-27-17-55-57-306.webp)
Evaluating an AI Document Extraction Solution
7. FAQs about AI document extraction solution
1 - Which AI tool is best for data extraction?
There is no single tool that is best for every use case. Enterprises should choose a platform based on their specific requirements:
Azure AI Document Intelligence: Well suited to financial documents and organizations using the Microsoft ecosystem.
Google Cloud Document AI: Suitable for document processing workflows built on Google Cloud.
Amazon Textract: A strong option for enterprises running their infrastructure and applications on AWS.
ABBYY Vantage: Suitable for complex document processing workflows that require data validation.
UiPath IXP: Best suited to use cases that combine document extraction with RPA and automated workflows.
Parseur: Optimized for automatically extracting data from emails and template-based PDFs, with fast integrations through Zapier and Make without requiring coding.
Docparser: An effective option for converting PDF and Word documents into structured data using fixed-position extraction with Zonal OCR.
2 - Can ChatGPT extract data from PDFs?
Yes. ChatGPT can process uploaded PDF files, extract text, tables, or specific information, summarize the content, and answer questions about the document. For scanned PDFs or files with complex layouts, accuracy may depend on the quality of the source file and the processing capabilities available under the user’s plan.
3 - How long does it take to build a custom AI document extraction solution?
A basic solution typically takes around four to eight weeks to build. More complex systems that process multiple document types and integrate with ERP, CRM, or internal workflows may take three to six months, depending on data quality, accuracy requirements, and the scope of implementation.
4 - What is the difference between traditional OCR and modern AI document extraction?
The table below compares traditional OCR and modern AI document extraction across several key criteria:
Criteria | Traditional OCR | Modern AI document extraction |
Primary function | Converts text in images or scanned documents into machine-readable text | Extracts and standardizes data from documents |
Processing capabilities | Often depends on fixed templates | Understands layouts, context, and multiple document formats |
Supported data types | Primarily recognizes text | Extracts text, tables, checkboxes, and key-value pairs |
Document classification | Usually requires separate configuration | Can automatically identify and classify documents |
Workflow integration | Requires additional processing after OCR | Can transfer data directly into business systems or automated workflows |
Investing in an advanced AI document extraction solution is a strategic step toward reducing manual workloads and optimizing business workflows. By extracting unstructured data quickly and accurately, enterprises can unlock valuable insights and strengthen their competitive advantage.
To ensure that the automation system operates effectively and integrates seamlessly with your existing infrastructure, contact TMA Solutions for consultation and a tailored AI implementation.
Contact information:
TMA SOLUTIONS - The leading provider of AI document extraction solutions in Vietnam Email: sales@tmasolutions.com Website: https://www.tmasolutions.com/ Linkedin: TMA Solutions TMA Tower address: Street #10, Quality Tech Solution Complex (QTSC), Trung My Tay Ward, Ho Chi Minh City. |